How to Monitor Bridging Aggregator Health Checks
 by
How to Monitor Bridging Aggregator Health Checks: A Complete Guide
Why Bridging Aggregator Health Checks Matter
In modern distributed architectures, microservice ecosystems, and decentralized data networks, a bridging aggregator acts as a critical link. It bridges disparate communication protocols, heterogeneous data formats, or independent networks, while simultaneously aggregating responses from multiple upstream and downstream services into a unified output. Because it sits directly in the execution path, the performance and reliability of the bridging aggregator determine the availability of the broader ecosystem.
A bridging aggregator presents a unique challenge for engineering and operations teams: a service can appear online while failing completely at its core functional duties. An HTTP status endpoint might continuously report operational status, yet the underlying system could be dropping payload transformations, failing to reach essential bridge endpoints, or returning partial, corrupted, or stale aggregations.
When health-check monitoring fails to detect these subtle operational degrades, the consequences propagate across the entire architecture:
-
Failed Bridge Operations: Transactions, state syncs, or message transformations fail silently, leading to broken workflows.
-
Delayed Data and Message Processing: Requests accumulate in processing queues, causing backpressure and extreme latency spikes across connected systems.
-
Increased Latency: Timeout cascading occurs when an aggregator waits for slow downstream bridge endpoints without proper fallback mechanisms.
-
Stale or Inconsistent Data: Partial aggregation failures return incomplete responses to clients without explicitly raising system-level errors.
-
Cascading Failures: Unhealthy aggregator instances consume excessive resources, exhausting connection pools and causing systemic outages across dependent services.
To guarantee true system resilience, monitoring must go beyond rudimentary ping tests. Effective observability requires evaluating availability, performance, dependency health, functional correctness, and automated recovery capabilities.
What Is a Bridging Aggregator Health Check?
A health check is a structured diagnostic probe executed periodically by an orchestrator, load balancer, or observability platform to determine whether an application instance can process traffic correctly. In a bridging aggregator context, a single static endpoint is rarely sufficient due to the complex multi-step pipeline involved in processing requests.
Health Check Classifications
Understanding the distinct roles of different health check types ensures accurate system diagnostic signals:
-
Liveness Checks: Verify whether the aggregator process is running and responsive. If a liveness probe fails, the hosting environment typically restarts the container or process. Liveness checks must remain light to prevent unintended restart loops during heavy load.
-
Readiness Checks: Determine whether the aggregator is prepared to accept live incoming traffic. A readiness check fails if the instance is initializing, executing warm-up routines, or briefly disconnected from essential local resources. Load balancers route traffic away from instances failing readiness checks.
-
Dependency Checks: Validate the reachability and operational status of external upstream endpoints, downstream data stores, message buses, and bridge targets.
-
Functional Checks: Test the actual end-to-end capabilities of the bridging aggregator. They execute synthetic test payloads through the validation, routing, bridge transmission, and aggregation pipeline to verify functional correctness.
Anatomy of a Multi-Stage Health Check Flow
A comprehensive bridging aggregator health check follows a defined operational sequence:
| Stage | Operation | Diagnostic Objective |
| 1. Reception | Probe hits internal health endpoint | Verifies HTTP server and thread pool availability |
| 2. Self-Validation | Inspect internal memory, queue depth, thread locks | Checks internal component health |
| 3. Dependency Probe | Ping active bridge target connections | Confirms reachability of upstream/downstream networks |
| 4. Functional Trial | Execute synthetic payload aggregation | Validates payload parsing and response merging logic |
| 5. Diagnostic Assembly | Compile detailed JSON status payload | Exposes granular metrics to observability collectors |
Relying solely on an endpoint returning HTTP 200 OK masks underlying bridge failures. A resilient health monitoring strategy dissects every stage of this execution pipeline.
Key Metrics to Monitor
Monitoring a bridging aggregator requires collecting, evaluating, and alerting on specific performance, operational, and system-level metrics.
Availability Metrics
Availability measures whether the aggregator and its core routing capabilities are accessible and functioning as expected across all deployment targets.
-
Health-Check Success Rate: The percentage of successful diagnostic probes over a defined time window.
-
Overall Uptime: Continuous duration of operational readiness across the aggregator cluster.
-
Failed Checks and Consecutive Failures: The exact tally of broken probes. Consecutive failures serve as the primary signal for marking an instance unhealthy.
-
Regional and Instance Availability: Segmented success rates across individual nodes, availability zones, and target bridge networks to isolate localized infrastructure issues.
Latency Metrics
Averages conceal critical performance degradation. Aggregator health checks must monitor latency distributions using percentiles:
-
p50 (Median) Latency: Represents the baseline response time for standard traffic.
-
p95 Latency: Highlights performance for the slowest 5 percent of operations, uncovering emerging bottlenecks.
-
p99 Latency: Detects extreme tail latency, often caused by garbage collection pauses, network jitter, or connection pool exhaustion.
-
Timeout Rate: The percentage of health probes or bridge executions that exceed pre-configured time limits.
Error Rates
Categorizing errors allows teams to quickly isolate whether failures stem from client inputs, aggregator logic, or downstream bridge endpoints:
| Category | Metric | Diagnostic Indication |
| Client Side | HTTP 4xx Errors | Invalid synthetic payloads, bad authentication tokens, schema mismatches |
| Server Side | HTTP 5xx Errors | Internal application crashes, unhandled exceptions, memory exhaustion |
| Network/IO | Connection Errors | DNS resolution failures, refused sockets, reset connection pairs |
| Dependencies | Downstream Failures | Unavailable bridge target endpoints, RPC timeouts, circuit breaker trips |
Throughput Metrics
Tracking throughput helps correlate health degradation with volume fluctuations:
-
Requests Per Second (RPS): Total volume of incoming requests processed by the aggregator layer.
-
Bridge Operations Count: Total number of successful versus failed outbound transactions across all active bridges.
-
Queue Processing Throughput: Rate at which queued payload aggregations are processed and cleared.
Resource Utilization
Hardware and operating system constraints directly impact health-check behavior:
-
CPU Utilization: High CPU usage causes thread starvation, delaying health-check responses and triggering false-positive failures.
-
Memory Usage and Heap Pressure: Unreclaimed memory leads to frequent garbage collection cycles, inducing severe tail latency.
-
Network Socket and Connection Pool Utilization: Depleted socket pools prevent the aggregator from initiating outbound connection probes to target bridges.
-
Thread/Worker Pool Saturation: Exhausted worker threads block incoming diagnostic checks at the HTTP server layer.
Aggregation-Specific Metrics
These specialized metrics target the operational integrity of the bridging layer itself:
-
Active vs. Healthy Bridge Connection Ratio: The total count of registered outbound bridge endpoints compared to those passing diagnostic checks.
-
Partial-Response Rate: The frequency with which the aggregator returns partial payloads because a subset of target bridges failed or timed out.
-
Stale Data Rate: Instances where cached or fallback data is served due to downstream reachability failures.
-
Retry Tally and Backoff Counts: Number of re-try attempts made by the aggregator when communicating with unstable bridge destinations.
-
Ingress/Egress Queue Depths: Unprocessed message accumulation indicating downstream processing delays.
Designing Effective Health Checks
Designing health checks for bridging aggregators requires balancing diagnostic depth with operational safety. Overly heavy health checks can degrade the performance of the very system they are meant to monitor.
Core Design Principles
-
Separate Diagnostic Concerns: Never combine liveness, readiness, and deep functional testing into a single endpoint. Use distinct endpoints like
/health/livenessfor process checks,/health/readinessfor connection readiness, and/health/functionalfor synthetic pipeline execution. -
Enforce Strict Timeout Thresholds: A health check probe must never block indefinitely. Set short, rigid timeouts on diagnostic queries (such as 500ms to 2000ms). If a check exceeds its window, it should fail immediately to prevent resource consumption.
-
Prevent Health Checks from Causing Self-Inflicted Load: If dozens of observability systems poll a deep diagnostic endpoint every second, the health checks themselves can trigger resource starvation. Implement response caching for internal dependency checks (e.g., caching downstream probe results for 5 to 10 seconds) so that frequent health endpoint hits read from memory rather than executing fresh upstream network calls.
-
Validate Response Structure and Content: Status codes alone are insufficient. An aggregator might return an HTTP 200 OK header while including an internal error message inside the response body. Health check engines must parse and validate the JSON payload content to verify actual success.
-
Handle Downstream Dependencies Independently: Implement circuit breakers for outbound bridge connections. If a single downstream bridge target fails, the health endpoint should report a degraded state rather than marking the entire aggregator instance offline, preventing unnecessary service restarts.
How to Monitor Bridging Aggregator Health Checks
Implementing robust monitoring for bridging aggregator health checks requires an organized, end-to-end technical strategy.
Step 1: Map Critical System Components
Map every component in the aggregator execution path before writing health probe code:
-
Aggregator Service Instances: The compute nodes running the aggregator code.
-
Bridge Endpoints: Outbound RPC, REST, or WebSockets connections to target networks and protocols.
-
Data Stores and Caches: Local databases, distributed caches, and state storage engines used for response aggregation.
-
Inbound and Outbound Queues: Message streaming platforms and buffer queues.
-
Authentication and Gateway Layers: Token verification services and upstream ingress proxies.
Step 2: Define Specific Health Indicators
Establish objective pass/fail metrics for each mapped component:
-
Primary Aggregator Endpoint: HTTP status equal to 200; total execution time under 500ms.
-
Target Bridge Reachability: Outbound handshake completion time under 1000ms; error rate under 1%.
-
Payload Validation: Synthetic test data parses successfully without schema validation errors.
-
Resource Thresholds: Memory consumption below 85% of assigned limits; thread pool queue length under 10 waiting jobs.
Step 3: Collect Comprehensive Health Telemetry
Gather telemetry across multiple diagnostic layers to ensure complete visibility:
-
Structured Metrics: Expose counter, gauge, and histogram endpoints formatted for collection engines like Prometheus or OpenTelemetry collectors.
-
Structured Logs: Output JSON-formatted log streams detailing health probe execution, failure reasons, and stack traces. Include contextual fields like
trace_id,bridge_target, andexecution_time_ms. -
Distributed Tracing: Contextually trace synthetic health requests as they move across the aggregator and outbound bridge calls to pinpoint structural latency bottlenecks.
Step 4: Centralize Dashboard Visualizations
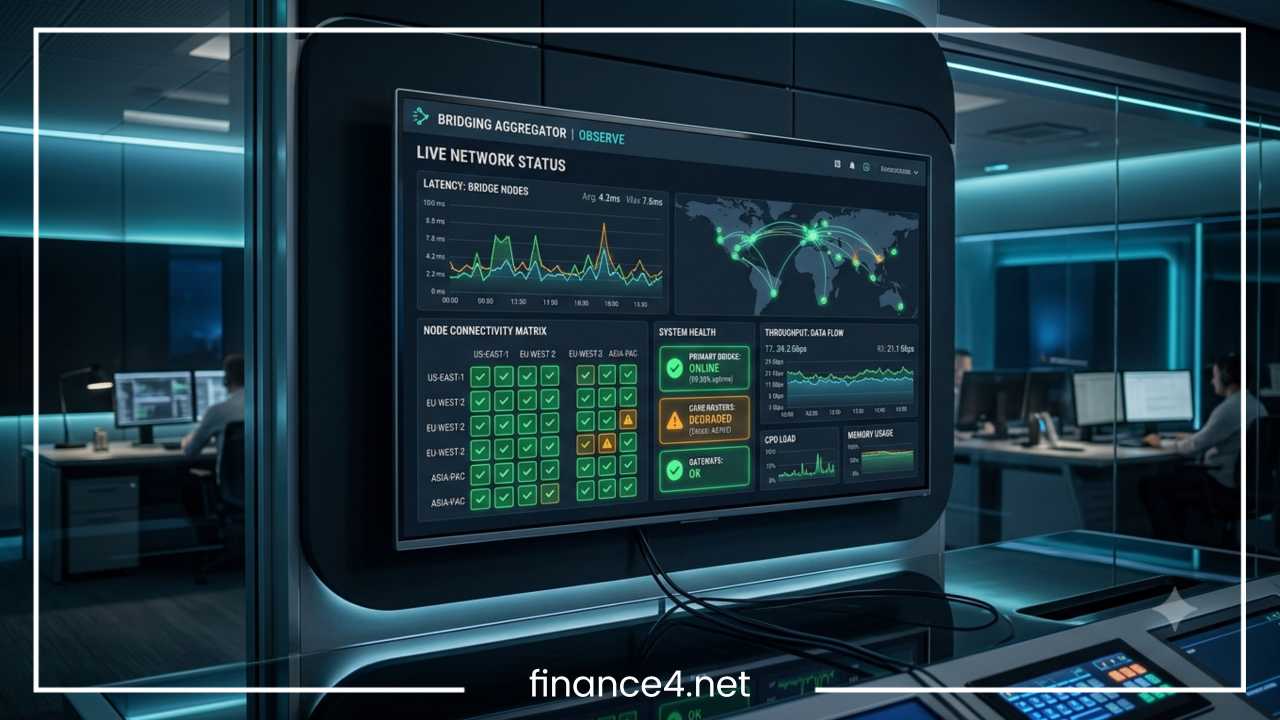
Construct dedicated, operational dashboards to display real-time diagnostic performance.
| Dashboard Metric | Diagnostic Value | Actionable Indicator |
| Health Check Success Rate | Overall system availability | Drops indicate widespread outage or network partitioning |
| p95 and p99 Latency | Identifies latency anomalies | Spikes highlight resource contention or slow downstream targets |
| HTTP 5xx Server Error Rate | Displays application failure frequency | Sudden increases point to bugs, unhandled exceptions, or crashes |
| Timeout Rate Trend | Measures communication degradation | High levels point to downstream bridge or network blockage |
| Dependency Health Matrix | Individual status of downstream targets | Highlights single-point-of-failure downstream endpoints |
| Queue Depth | Processing backlog status | Growing depth indicates processing bottlenecks |
| Resource Utilization | Memory and CPU load levels | Saturation signals need for vertical or horizontal scaling |
Step 5: Establish Baseline Operating Curves
Avoid setting static thresholds based purely on initial assumptions. Analyze historical telemetry under varying operational conditions:
-
Observe metric variances during peak traffic times versus off-peak hours.
-
Document normal performance degradation during expected traffic spikes.
-
Differentiate between temporary network jitter and sustained system degradation.
-
Set alert thresholds based on historical standard deviations rather than arbitrary numbers.
Step 6: Configure Actionable Alerting Policies
Structure alerting mechanisms to notify the appropriate engineering personnel based on incident severity:
-
Route critical outage alerts directly to active incident response channels and on-call rotation systems.
-
Route warnings or minor performance degrades to team communication channels for review during business hours.
-
Ensure every alert contains explicit links to relevant dashboards, runbooks, and diagnostic log queries.
Monitoring Tools and Observability Stack
An effective observability stack relies on specialized, interoperable components working together:
Metrics Collection
Prometheus, Datadog, and cloud-native monitoring agents poll application metrics exposed by the bridging aggregator. They efficiently track time-series numeric data, counter trends, and percentiles over time.
Dashboarding and Visualization
Grafana and equivalent enterprise platforms visualize metrics scraped from monitoring systems. Dashboards give engineering teams real-time visibility into system behavior and health check trends across environments.
Log Management and Analysis
Centralized log platforms (such as the ELK Stack, OpenSearch, or Loki) ingest structured JSON logs from aggregator instances. When a health check fails, engineers query these logs to inspect exact error messages and context.
Distributed Tracing
OpenTelemetry, Jaeger, and Zipkin track individual requests as they travel across distributed network boundaries. Tracing isolates whether a health check latency spike originated inside the local aggregator’s parsing logic or within a specific downstream bridge endpoint.
Alert Engine Integration
Tools like Alertmanager, PagerDuty, and Opsgenie process alert rules generated by metrics engines. They route notifications to on-call engineers via SMS, push notifications, or collaboration tools like Slack and Microsoft Teams based on defined escalation policies.
Triad Operational Value
The core observability workflow uses these components sequentially:
-
Metrics detect the problem: A metric graph highlights a spike in diagnostic check failures.
-
Traces locate the problem: Distributed traces reveal that outbound calls to a specific target bridge are timing out.
-
Logs explain the problem: Log entries reveal connection refused errors originating from an expired TLS certificate on the target bridge.
Setting Health-Check Thresholds and Alerts
Poorly configured alerting leads to alert fatigue, causing engineers to ignore critical notifications. Configuring clear thresholds based on problem severity prevents missed incidents while reducing noise.
Defining Threshold Categories
Structure alert rules using distinct severity levels:
-
Warning Level: Indicates early degradation that does not immediately disrupt client operations. For example, a single health probe timeout, CPU utilization exceeding 75% for 5 minutes, or p95 latency increasing by 20%.
-
Critical Level: Indicates active service failure, data loss risk, or severe availability loss. For example, three consecutive health probe failures across 50% of cluster nodes, failure of all primary downstream bridge connections, or p99 latency exceeding maximum allowable limits.
Recommended Threshold Rules for Bridging Aggregators
| Diagnostic Metric | Warning Threshold | Critical Threshold | Evaluation Window |
| Health Check Failure Tally | 2 consecutive failed probes | 5 consecutive failed probes | 1-minute window |
| p95 Latency | Exceeds 1,000ms | Exceeds 3,000ms | Sustained for 3 minutes |
| HTTP 5xx Rate | Exceeds 1% of total requests | Exceeds 5% of total requests | Sustained for 2 minutes |
| Downstream Bridge Reachability | 1 target bridge unreachable | Exceeds 30% of target bridges unreachable | Evaluated instantly |
| Memory Consumption | Exceeds 80% allocated heap | Exceeds 92% allocated heap | Sustained for 5 minutes |
Strategies for Reducing Alert Noise
-
Require Consecutive Failure Counts: Never trigger a critical alert based on a single failed health probe. Require at least two or three consecutive failures to rule out transient network blips.
-
Incorporate Hysteresis into Alerting Rules: Require metrics to drop cleanly below a target threshold before auto-resolving an incident, preventing rapid firing and resolving loops.
-
Separate Dependency Outages from Local Failures: If a downstream target bridge goes down, fire a specific dependency unreachable alert rather than a generic aggregator process dead notification.
-
Implement Maintenance Window Suppressions: Mute non-critical alerts during scheduled deployment windows or known system maintenance periods.
Troubleshooting Bridging Aggregator Health-Check Failures
When a health check alert fires, incident responders need a clear, structured workflow to diagnose and resolve the root cause quickly.
Systematic Troubleshooting Steps
-
Assess the Blast Radius: Determine if the health check failure is isolated to a single container instance or affecting the entire aggregator fleet. Isolated failures usually point to node-level infrastructure or memory issues, while widespread failures suggest dependency outages or bad configurations.
-
Review Recent Deployments and Changes: Check if new code, updated environment variables, or schema updates were recently deployed to the environment.
-
Inspect Downstream Bridge Reachability: Verify whether external bridge endpoints, third-party APIs, or target network nodes are active and reachable from the aggregator network segment.
-
Examine System Resource Utilization: Inspect CPU utilization, memory pressure, open file descriptor counts, and socket pool limits on failing nodes.
-
Analyze Application Logs: Search centralized logs for error traces, unhandled exceptions, timeout warnings, or failed validation messages around the time of the incident.
-
Follow Distributed Traces: Trace sample failed synthetic health checks to pinpoint where the pipeline stalled or threw an exception.
-
Check Network Connectivity and DNS: Verify that internal and external DNS resolution works correctly and that firewall rules or security groups haven’t changed.
-
Evaluate Automated Recovery Actions: Confirm whether automated container restarts or load balancer deregistrations triggered correctly and whether they resolved the issue.
Common Root Causes and Quick Fixes
| Observed Symptom | Likely Root Cause | Remediation Action |
| Probe times out consistently | Exhausted worker thread pool or locked thread state | Increase thread pool capacity; review code for blocking IO calls |
| HTTP 500 on health endpoint | Unhandled exception during dependency check | Add robust error handling around health check dependency calls |
| Intermittent health failures | GC pauses causing temporary service freezes | Tune memory allocation and garbage collection parameters |
| Health check passes, but bridge fails | Health endpoint doesn’t test actual bridge execution | Upgrade probe to execute functional synthetic transactions |
| Failures after deployment | Misconfigured environment variables or credentials | Roll back deployment; verify credential configurations |
Best Practices for Reliable Health-Check Monitoring
Building a resilient health-check monitoring architecture requires following established operational best practices:
-
Implement Layered Diagnostic Probes: Keep process liveness checks lightweight, use readiness checks to monitor dependency connections, and run deeper functional checks on separate schedules.
-
Monitor Dependencies Independently: Trace downstream bridge endpoints on their own metrics channels so external outages don’t obscure local aggregator health.
-
Analyze Performance Trends: Track percentiles over time rather than relying solely on real-time pass/fail indicators to identify performance degradation early.
-
Use Percentile Latencies Over Averages: Rely on p95 and p99 latency metrics to expose tail latency issues hidden by average metrics.
-
Correlate Metrics, Logs, and Traces: Ensure telemetry data shares common contextual tags (such as instance ID, environment, and trace ID) for fast cross-investigation during incidents.
-
Keep Diagnostic Endpoints Lightweight: Cache internal dependency checks briefly to prevent diagnostic queries from creating high CPU or network load.
-
Test Alerting and Escalation Pathways: Conduct chaos engineering tests to confirm that simulated health check failures trigger the right alerts and escalation channels.
-
Maintain Clear Incident Runbooks: Link explicit troubleshooting instructions directly to every health check alert rule.
-
Review Thresholds Regularly: Periodically evaluate and adjust health thresholds as traffic patterns, code, and system architecture evolve.
-
Monitor System Recovery: Alert on recovery events to verify that self-healing mechanisms restore services to a stable operational state.
How to Build a Health-Check Monitoring Dashboard
A well-structured dashboard helps engineers quickly assess system status during an incident. Organize metrics logically into distinct visual sections:
| Dashboard Section | Component Metrics | Primary Diagnostic Focus |
| Top Row: System Overview | Global status indicator, overall availability percentage, active incident count | Immediate status assessment and business impact evaluation |
| Second Row: Performance & Latency | p50, p95, and p99 latency trends, HTTP 2xx/4xx/5xx request rates | Identifying latency spikes and service error frequencies |
| Third Row: Dependency Health | Healthy bridge endpoint ratios, downstream failure rates, queue depths | Pinpointing failing target bridges and message processing bottlenecks |
| Bottom Row: Infrastructure & Events | CPU load, memory utilization, socket pools, deployment markers | Correlating hardware exhaustion or recent code updates with failures |
Improving Your Monitoring Strategy Over Time
Monitoring is an ongoing process that must evolve alongside your software and infrastructure architecture.
Continuous Refinement Steps
-
Conduct Post-Incident Reviews: Analyze health-check telemetry after every production outage. Identify whether existing probes detected the failure promptly or if new diagnostic tests are needed.
-
Refine Thresholds to Reduce Noise: Regularly adjust alert thresholds to eliminate false positives and reduce alert fatigue for on-call teams.
-
Expand Synthetic Probe Coverage: As new features, bridge destinations, or protocols are added, update functional health checks to cover these new components.
-
Run Automated Chaos Experiments: Periodically inject artificial network latency, drop bridge connections, or crash individual instances to verify that health checks identify issues and trigger appropriate alerts.
-
Track Long-Term Performance Trends: Analyze quarterly telemetry to spot gradual performance degradation, resource leaks, or shifting traffic patterns before they cause outages.
Final Thoughts
Monitoring a bridging aggregator effectively requires moving beyond basic ping tests and static status codes. Because aggregators sit at the intersection of multiple systems, verifying that a service process is running is only the first step. True operational visibility requires confirming that the aggregator is available, responsive, properly connected to its dependencies, processing payloads accurately, and able to recover automatically when failures occur.
By implementing multi-tiered health checks, monitoring key percentiles, centralizing observability data, and setting clear, actionable alerts, engineering teams can build a resilient framework for How to Monitor Bridging Aggregator Health Checks. This proactive strategy ensures high availability, minimizes unexpected downtime, and protects the stability of the broader system.
Frequently Asked Questions
What is the difference between liveness and readiness health checks for a bridging aggregator?
A liveness check determines whether the bridging aggregator application process is running and active. If a liveness probe fails, orchestrators like Kubernetes automatically restart the container. A readiness check determines whether the aggregator is actually capable of accepting incoming traffic, verifying that required local resources, warm-up tasks, and initial network interfaces are ready. Load balancers route traffic away from instances that fail readiness checks without restarting the process.
How do you test downstream dependency health without causing health check failure loops?
To monitor downstream bridge target health safely, decoupling dependency checks from liveness probes is essential. Use dedicated readiness or functional diagnostic endpoints with response caching (such as caching downstream connection status for 5 to 10 seconds). Implementing circuit breakers prevents temporary downstream timeouts from causing cascading failures across your aggregator fleet.
Why does a bridging aggregator return HTTP status 200 when internal bridge calls are failing?
An HTTP status 200 OK simply confirms that the aggregator server successfully received and processed the diagnostic request. If the health check logic fails to execute synthetic payload tests against downstream bridges, it can report an operational HTTP 200 status code even when internal transformations, target network handshakes, or response aggregation pipelines are completely broken.
How often should you run health checks on cross-chain and cross-network bridging aggregators?
Liveness probes should execute frequently (every 5 to 10 seconds) with short timeouts to ensure fast process recovery. Deep functional checks and synthetic bridge payload tests should run every 30 to 60 seconds with cached dependency results to prevent diagnostic probes from creating excessive self-inflicted system load.
What are the best metrics to alert on for bridging aggregator performance degradation?
Focus on latency percentiles (p95 and p99 response times), http 5xx server error rates, consecutive health-check failures, and bridge connection success ratios. Tracking p95 and p99 percentiles instead of average latency exposes tail latency issues caused by network jitter or thread starvation before total system failure occurs.
How do you fix false-positive health check alerts in Kubernetes and cloud load balancers?
False positives usually stem from aggressive polling intervals, excessively tight timeout windows, or CPU starvation during peak loads. Fix false positives by configuring consecutive failure thresholds (requiring 3 to 5 failed probes before taking an instance offline), widening timeout limits to match normal p99 latencies, and separating process liveness probes from heavy dependency checks.