How to Track Bridging Aggregator Performance
 by
How to Track Bridging Aggregator Performance | Key Metrics & Guide
Cross-chain infrastructure has transformed from a sparse network of basic point-to-point bridges into a complex ecosystem powered by bridging aggregators. These protocol layers scan multiple cross-chain paths, liquidity pools, and messaging protocols to route user funds across distinct blockchain networks. However, evaluating the actual execution quality of a bridging aggregator requires moving far beyond simple top-line figures. Tracking total processed volume or marketing headline speed numbers rarely paints an accurate picture of real-world efficiency, security, or user cost.
To understand how effectively an aggregator performs, operators, developers, protocols, and institutional users must establish robust measurement practices. Evaluating cross-chain aggregation requires a multi-dimensional approach that looks deep into execution mechanics, underlying liquidity depth, transaction completion rates, and quote fidelity. A complete operational assessment relies on looking across execution, liquidity, cost, reliability, speed, user experience, and security.
Learning how to track bridging aggregator performance provides the analytical clarity needed to optimize routing algorithms, reduce user friction, lower operational costs, and prevent costly transaction failures. This guide delivers a comprehensive blueprint for defining core key performance indicators (KPIs), collecting multi-chain data, building actionable dashboards, and translating raw blockchain analytics into performance-improving insights.
What Is Bridging Aggregator Performance?
A bridging aggregator is a software layer or protocol that interfaces with multiple underlying cross-chain bridges, decentralized exchanges (DEXs), and liquidity networks. Rather than forcing users to manually research which bridge offers the cheapest or fastest transfer from Network A to Network B, the aggregator queries multiple routes, computes gas costs and slippage, and executes the transfer via the optimal path.
Individual bridges operate with static infrastructure, dedicated liquidity pools, or specific messaging frameworks (such as lock-and-mint, burn-and-mint, or atomic swaps). Aggregators sit above these single-bridge primitives, dynamic routing logic to bundle cross-chain messaging, token swaps, and fee payments into unified user workflows.
In this architecture, performance represents the holistic efficiency, accuracy, and reliability with which the aggregator executes cross-chain requests relative to optimal market conditions. Performance cannot be reduced to a single isolated metric like raw transaction throughput or minimal front-end fees. A bridge route might offer zero aggregator fees but suffer from high failure rates, severe slippage on large orders, or prolonged latency during network congestion.
A structured evaluation views performance through an integrated lens:
Performance = Cost + Speed + Success Rate + Liquidity + Reliability + User Experience + Risk
Evaluating each component within this framework prevents deceptive optimizations—such as routing through cheaper paths that carry unacceptable security risks or routing through ultra-fast bridges that cause severe slippage.
Why Track Bridging Aggregator Performance?
Relying on a single snapshot or trusting static claims from underlying bridge providers leaves protocols and users vulnerable to unexpected costs, stuck transactions, and poor execution. Continuous, historical performance tracking yields strategic and operational benefits across the Web3 stack:
-
Users: Historical tracking ensures lower overall transaction costs, minimizes slippage, prevents stuck funds, and reduces user error through accurate completion estimates.
-
Protocols and dApps: Embedded bridging widgets or white-label cross-chain solutions directly impact product retention. High bridge failure rates lead to abandoned dApp onboarding flows and broken cross-chain user journeys.
-
Liquidity Providers: Tracking capital turnover, pool utilization, and routing preferences helps liquidity providers allocate assets where yields are maximized and idle capital is minimized.
-
Aggregator Operators: Real-time metrics expose failing RPC nodes, lagging relayers, depleted liquidity pools, and suboptimal routing logic, allowing engineers to patch issues before users experience disruptions.
-
Developers: Granular execution data allows developers to refine routing algorithms, balance multi-step swap logic, and calibrate gas estimation models.
-
Businesses and Enterprises: Treasury managers and institutional desks require verifiable execution benchmarks to satisfy compliance, risk management, and execution mandates.
Single-transaction checks only indicate what happened at one isolated moment. Systematic, historical performance monitoring reveals systemic routing bugs, latency trends during peak network load, and subtle degradation in execution quality over time.
Key Metrics for Tracking Bridging Aggregator Performance
Tracking bridging aggregator performance requires a granular breakdown of operational metrics. Evaluating these twelve key metrics establishes a holistic performance baseline.
1. Transaction Volume
Transaction volume reflects the total economic activity routed through the aggregator over defined timeframes (daily, weekly, monthly). When measuring volume, separate raw transaction counts from aggregate USD value:
-
Number of Bridge Transactions: Total count of individual cross-chain transfers initiated and processed.
-
Total Transferred Value: Aggregate USD value of all assets moved across chains.
-
Volume by Chain Pair: Breakdown of transfer volumes between specific source and destination networks (e.g., Ethereum to Arbitrum vs. Polygon to Avalanche).
-
Volume by Token: Distribution of asset types routed through the system (e.g., stablecoins vs. volatile native assets).
Transaction count and economic volume frequently diverge. A high transaction count paired with low total value indicates retail usage or micro-transfers, whereas low transaction counts with massive transfer values signal institutional or whale usage. Analyzing this balance reveals whether your aggregator’s routing algorithms are optimized for low gas overhead or deep liquidity execution.
2. Transaction Success Rate
Transaction success rate measures the percentage of initiated bridging operations that finalize successfully on the destination chain without manual intervention or failure.
To calculate the baseline success rate:
Success Rate = (Successful Transactions / Total Transactions) * 100
Evaluating success rates requires analyzing where along the route a failure occurred. Distinguish between failures originating on the source chain (e.g., insufficient user gas or user-cancelled transactions) and failures caused by bridge relayers, smart contract reverts, or destination-chain execution errors.
Transactions that get temporarily stuck, require manual claim signatures, or rely on fallback routes must be tracked in a dedicated “delayed or degraded” category rather than lumped directly into simple binary success or failure stats.
3. Bridging Transaction Time
Cross-chain latency spans the moment a user signs the transaction on the source chain to the exact block timestamp where funds become fully usable on the destination chain.
Relying solely on average completion time creates a major analytical blind spot. A few fast 10-second layer-2 transfers heavily skew the arithmetic mean, masking outlier transactions that take hours to complete. A proper speed audit evaluates:
-
Average Completion Time: General overview metric for macro trends.
-
Median Completion Time (P50): Represents the true typical experience for a standard user.
-
P90 / P95 Completion Time: Measures tail latency, highlighting worst-case scenarios caused by block finality delays, relayer queues, or network congestion.
-
Latency by Chain Pair & Provider: Isolates speed bottlenecks to specific chain finality rules (e.g., Ethereum L1 reorg protection) or lagging relayer networks.
4. Total Bridging Cost
Focusing exclusively on the upfront fee charged by the aggregator distorts actual user expenses. A low fee is irrelevant if bad gas estimates or inefficient contract execution inflate secondary costs.
Tracking true bridging cost requires aggregating every fee component in the execution pipeline:
-
Aggregator & Bridge Protocol Fees: Flat or percentage-based service fees collected by the routing software and underlying bridge.
-
Source-Chain Gas Fees: Network execution fees required to approve and deposit funds into the source contract.
-
Destination-Chain Gas Fees: Fees consumed to claim, mint, or release assets on the destination network (often paid directly by relayers and bundled into the total price).
-
Relayer & Messaging Fees: Costs charged by third-party oracle or messaging networks (e.g., LayerZero, Chainlink CCIP, Axelar) for transmitting cross-chain proofs.
-
DEX Swap & Token Conversion Costs: Fees incurred if the aggregator performs a pre-bridge swap on the source chain or a post-bridge swap on the destination chain.
-
Slippage Impact: Economic value lost during asset conversions across the route.
The metric that truly matters for user retention is the total cost to user, representing the absolute difference between the starting asset value on the source chain and the net asset value received on the destination chain.
5. Slippage
Slippage occurs when the final asset output amount on the destination chain differs from the estimated output shown during transaction initiation. In cross-chain bridging, slippage manifests during both automated market maker (AMM) swaps and dynamic bridge liquidity pool conversions.
Key slippage metrics include:
-
Slippage Percentage: The variance between expected asset output and actual received output.
-
Slippage by Token & Route: Pinpoints low-liquidity pools or poorly calibrated swap paths.
-
Slippage During Volatility: Measures how execution degradation scales during market shocks when pool ratios shift rapidly.
-
Quoted vs. Executed Price Difference: Isolates execution drag caused by delays between transaction signature and contract execution.
Slippage tracking is crucial for institutional transactions, where even a 0.5% execution variance on a large transfer can outweigh all protocol and gas fees combined.
6. Liquidity Availability
An aggregator’s performance is strictly bounded by the liquidity depth of the underlying bridges and DEXs it queries. Insufficient liquidity forces routes to split across inferior paths or fail entirely.
Key liquidity performance metrics:
-
Available Liquidity per Route: Real-time depth of destination pools for specific token pairs.
-
Liquidity Depth & Market Impact: The trade size threshold required to shift output prices by 1%, 2%, or 5%.
-
Insufficient Liquidity Event Frequency: Count of user queries or attempts that failed or reverted due to depleted target pools.
-
Liquidity Distribution: Asset dispersion across connected networks and bridge vaults.
Monitoring these factors reveals when poor aggregator performance stems from external pool depletion rather than flaws in the routing logic itself.
7. Route Quality
Because aggregators choose from multiple bridges, route quality analytics determine whether the system consistently routes users through optimal paths.
For every completed transaction, compare the selected route against alternative routes that were available at the time of execution. Track execution cost, total latency, success rate, and slippage for each candidate bridge. If analysis reveals that the aggregator repeatedly selects paths with higher failure rates or greater total costs when cleaner, faster options were active, the routing algorithm requires recalibration.
8. Quote-to-Execution Accuracy
Quote-to-Execution accuracy evaluates how faithfully the aggregator’s pre-transaction estimate predicts the actual post-transaction outcome.
| Metric Component | Quoted Value (Pre-Transaction) | Actual Value (Post-Transaction) | Variance Tracking Goal |
| Asset Output | Expected token delivery | Received token delivery | Minimize output deficit |
| Total Cost | Estimated gas + protocol fees | Actual combined gas + fees | Eliminate unexpected costs |
| Latency | Estimated delivery time | Realized completion time | Prevent false speed expectations |
High quote variance damages trust. If an aggregator promises 30-second completion for $2 in fees but consistently delivers 5-minute transactions costing $8, users will abandon the platform—even if the transaction ultimately succeeds.
9. Gas Efficiency
Gas efficiency measures how effectively smart contracts execute routing, token approvals, and cross-chain calls without wasting block space or computational step units.
Key gas metrics:
-
Gas Units Used per Transaction: Raw computational cost of contract execution on EVM and non-EVM chains.
-
Gas Overhead by Route: Compares smart contract complexity across different bridge wrapper implementations.
-
Gas-to-Value Ratio: Evaluates whether small-value transfers consume disproportionate gas relative to the principal transferred.
Optimizing gas efficiency involves identifying redundant token allowance calls, streamlining multi-hop smart contract logic, and avoiding unnecessary intermediate wrapping or unwrapping steps.
10. Route Failure and Error Rates
Tracking overall success rates provides a high-level overview, but route failure analysis diagnoses specific underlying operational issues. Segment failures into precise diagnostic categories:
-
RPC Node Errors: Failures caused by dropped provider connections or delayed state reads.
-
Relayer Latency / Timeouts: Messages stalled in transit between source and target networks.
-
Liquidity Depletion Reverts: Smart contracts reverting due to insufficient pool depth on the destination chain.
-
Slippage Tolerance Violations: Swaps reverting because market prices moved beyond user-defined parameters.
-
Gas Estimation Failures: Transactions running out of gas mid-execution on the target chain.
-
User Cancellations: Transactions aborted prior to source-chain execution.
Categorizing errors prevents engineering teams from wasting time debugging smart contracts when the root issue is actually an unstable third-party relayer or miscalibrated RPC endpoint.
11. Liquidity Utilization and Capital Efficiency
For protocols operating their own bridging pools alongside aggregated routes, capital efficiency measures how productively deployed assets generate volume:
-
Capital Deployed per Route: Total value locked (TVL) allocated to sustain cross-chain channels.
-
Liquidity Turnover Ratio: Total volume processed over a given timeframe divided by available TVL.
-
Idle Liquidity Percentage: Assets sitting inactive in target contracts without generating routing yield or supporting transfer volume.
-
Peak Traffic Capacity: Maximum volume a route can settle before experiencing pool exhaustion or severe price impact.
High TVL with low volume indicates underutilized capital, whereas high turnover with low TVL signals efficient liquidity usage—provided pool slippage remains within acceptable bounds.
12. User Experience Metrics
Technical performance on-chain does not always align with user-perceived quality. Tracking user experience (UX) metrics highlights front-end and interface performance bottlenecks:
-
Quote Response Time: Latency required for the aggregator’s API to fetch, calculate, and display optimal routes to the user.
-
Transaction Initiation Time: Delay between user signature approval and initial source-chain broadcast.
-
UI Completion Feedback Latency: Time elapsed between on-chain destination finality and UI state confirmation.
-
Abandonment Rate: Percentage of users who request a route quote but abandon the workflow before signing.
-
Support Ticket Volume: Rate of user inquiries triggered by delayed, stuck, or failed transfers.
How to Measure Bridging Aggregator Performance
Accurately measuring bridging aggregator performance requires combining source-chain events, destination-chain logs, off-chain API metrics, and user interface tracking into a unified data pipeline.
Collect On-Chain Data
On-chain data serves as the source of truth for transaction finality, fee consumption, and execution mechanics. To collect comprehensive on-chain records, index data from both source and destination chains:
-
Extract transaction hashes, block numbers, and exact block timestamps on both origin and target networks.
-
Capture smart contract event logs for deposit, messaging dispatch, token minting/unlocking, and destination delivery.
-
Read exact gas consumption, effective gas prices, and token transfer event values directly from chain receipts.
Combine On-Chain and Aggregator Data
On-chain state logs reveal what occurred during execution, but they miss crucial context about pre-transaction conditions. On-chain data alone cannot tell you:
-
What the original quoted output or estimated completion time was.
-
Which alternative routes were available when the order was placed.
-
Whether a transaction failed due to user abandonment or API latency prior to contract submission.
Integrate on-chain records with aggregator backend API logs, relayer state feeds, and front-end telemetric data. Matching off-chain quotes to final on-chain transaction outcomes enables true quote-to-execution variance analysis.
Build a Route-Level Dataset
To run structured analytical queries, assemble your combined data into a normalized route-level record format:
| Field | Description | Measurement Purpose |
transaction_id |
Unique internal UUID or source tx hash | Uniquely identifies individual transfers |
timestamp_initiated |
UTC timestamp of initial user sign | Measures total latency start point |
timestamp_completed |
UTC timestamp of final target block | Measures total latency end point |
source_chain |
Origin network (e.g., Arbitrum) | Isolates source-chain conditions |
destination_chain |
Target network (e.g., Optimism) | Isolates destination-chain conditions |
token_sent |
Input asset contract address & symbol | Tracks volume by asset type |
token_received |
Output asset contract address & symbol | Verifies asset conversions |
selected_route |
Underlying bridge and DEX path used | Evaluates provider-level execution |
amount_in |
Raw input token units | Measures transfer size |
amount_out_quoted |
Expected output tokens from API | Establishes baseline execution quote |
amount_out_actual |
Net tokens received on target chain | Measures execution slippage |
total_cost_usd |
Combined gas + protocol + relayer cost | Calculates true user expense |
status |
SUCCESS, FAILED, DELAYED, REVERTED | Evaluates path reliability |
error_code |
Categorized cause of failure | Pinpoints system failure modes |
How to Build a Bridging Aggregator Performance Dashboard
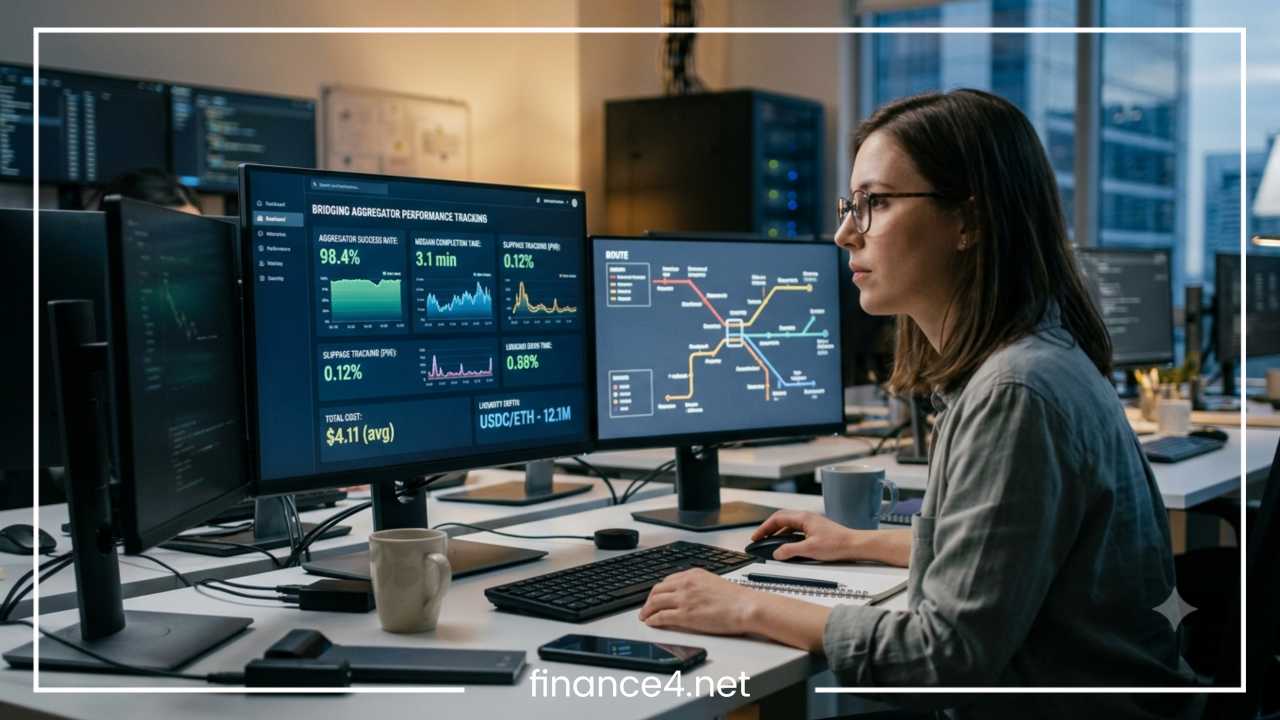
A well-architected dashboard converts raw cross-chain logs into clear operational insights. Organize your reporting interface into four distinct analytical views:
1. Overview Metrics Panel
High-level operational health indicators updated in real time:
-
Aggregated 24-hour and 30-day transaction volume ($ USD).
-
System-wide transaction success rate (%).
-
Median and P95 completion times across all routes.
-
Average user execution cost ($ USD) and average slippage (%).
2. Route-Level Performance View
Granular breakdown comparing connected bridge protocols:
-
Top performing vs. underperforming bridge protocols sorted by volume and success rate.
-
Comparative latency curves across different bridging providers.
-
Failure rate heatmaps categorized by route and underlying liquidity pool.
3. Chain-Level & Pair Analysis
Network-specific mapping to identify regional infrastructure bottlenecks:
-
Source-to-destination volume matrix (e.g., Ethereum -> Polygon vs. Base -> Solana).
-
Chain-pair latency and gas overhead trends.
-
Network congestion alerts indicating RPC or relayer slowdowns.
4. Time-Series & Anomaly Detection View
Longitudinal tracking to catch performance degradation over time:
-
Historical success rate trends overlaid with network gas spikes.
-
Latency changes following major protocol or chain network upgrades.
-
Automated alert logs highlighting abnormal drops in route liquidity or spikes in quote variance.
Visualizing these views using line charts for latency percentiles, heatmaps for route failure rates, and stacked bar charts for cost breakdowns helps teams make data-driven routing decisions.
How to Compare Bridging Aggregator Performance
When benchmarking multiple bridging aggregators, evaluating total volume alone yields misleading results. Aggregators processing high volumes on low-cost Layer 2 networks appear faster and cheaper than those routing complex assets across less liquid Layer 1 chains.
To build an accurate benchmark, standardize evaluation parameters across all target aggregators:
-
Hold Variables Constant: Compare execution quality using identical chain pairs, identical token assets, equivalent order sizes, and concurrent execution windows.
-
Evaluate Relative Cost vs. Speed: Map platforms on a cost-versus-speed matrix to evaluate trade-offs.
-
Test Multiple Order Volumes: Test micro-transfers ($50), standard retail orders ($1,000), and large liquidity transfers ($100,000+) to reveal where slippage and liquidity constraints emerge.
-
Measure Quote Reliability: Benchmark how accurately each aggregator predicts actual final output and gas requirements under fluctuating market conditions.
Common Mistakes When Tracking Bridging Aggregator Performance
Avoiding common data analytical errors prevents teams from drawing incorrect conclusions about system health:
-
Measuring Volume Alone: Assuming high transaction volume implies high system quality. High volume can obscure severe failure rates on lower-volume niche routes.
-
Relying Exclusively on Average Metrics: Using standard averages for speed and cost instead of median (P50) and high-percentile (P95) metrics, masking critical tail-end latency spikes.
-
Ignoring Failed Transactions (Survivorship Bias): Calculating average cost or completion speed using only successful transfers, completely ignoring the time and gas lost on failed transactions.
-
Ignoring Order Size Sensitivity: Failing to segment performance by transfer size, missing the fact that small orders are sensitive to gas overhead while large orders are sensitive to slippage.
-
Combining Heterogeneous Chains: Aggregating performance data across fundamentally different network architectures (e.g., L2-to-L2 sidechannels vs. mainnet L1-to-L1 settlement paths) without proper segmentation.
-
Ignoring Temporal Context: Comparing routes without accounting for real-time network congestion or gas price volatility.
-
Relying Solely on On-Chain Data: Neglecting off-chain API logs, leaving teams blind to quote variances, pre-chain user drop-offs, and UI latency issues.
-
Treating All Failures Identically: Grouping user signature rejections together with critical smart contract reverts or relayer timeouts.
How to Improve Bridging Aggregator Performance Based on the Data
Tracking performance metrics is only valuable if the data drives concrete operational improvements. The table below maps common performance bottlenecks to their metric indicators and strategic fixes:
| Performance Problem | Primary Metrics to Investigate | Diagnostic Action & Operational Response |
| Excessive user costs | Total cost to user, gas units used, DEX swap fees | Recalibrate routing logic to bypass multi-hop swaps; batch smart contract calls to reduce gas overhead. |
| Prolonged transfer delays | P95 latency, completion time by bridge, relayer logs | Dynamically deprioritize slow or congested bridge paths; implement automated relayer timeout fallbacks. |
| Elevated failure rates | Success rate by route, failure error types | Remove unstable bridge pools from routing index; adjust gas estimation buffers to eliminate out-of-gas errors. |
| Unexpected slippage | Output variance, pool depth impact, route slippage | Set dynamic slippage caps based on order size; route large transfers through private solver networks or split routes. |
| Inaccurate user quotes | Quote-to-execution variance | Update off-chain state fetching rates; incorporate real-time gas price volatility adjustments into quote engines. |
| Depleted route liquidity | Liquidity availability, target pool depth | Program routing engines to split multi-million dollar transfers across multiple distinct bridge protocols simultaneously. |
| Route selection bias | Volume distribution by bridge, route quality comparison | Re-weight routing algorithms to prioritize real-time execution quality over static fee structures. |
A Practical Bridging Aggregator Performance Tracking Framework
To implement a reliable long-term performance monitoring pipeline, establish this structured eight-step operational workflow:
Step 1: Define Target Key Performance Indicators (KPIs)
Select core metrics aligned with your platform’s goals. Prioritize transaction success rate, median latency, total cost to user, and quote accuracy.
Step 2: Establish Measurement Windows
Set up multi-tiered tracking intervals: real-time monitoring for automated operational alerts, daily rollups for route optimization, and monthly audits for broad infrastructure reviews.
Step 3: Build Unified Data Collection Pipelines
Deploy open-source data indexers or custom RPC event listeners to capture on-chain logs across all supported networks. Pipeline these logs alongside off-chain API quote outputs into a centralized analytical database.
Step 4: Normalize Cross-Chain Data
Standardize asset values into USD, convert disparate block timestamps to UTC, normalize chain naming conventions, and categorize raw error strings into unified failure codes.
Step 5: Segment Analysis
Group incoming data by chain pair, asset volatility, transaction size tier (e.g., micro, standard, whale), and routing protocol to ensure apples-to-apples comparisons.
Step 6: Establish Historical Baselines
Calculate rolling 30-day historical benchmarks for each route. Base operational alerts on deviations from these internal baselines rather than arbitrary external industry estimates.
Step 7: Configure Automated Anomaly Monitoring
Set up automated alerts for critical system shifts, such as success rates dropping below 98%, P95 latency exceeding double the baseline, or quote output variance spiking above 1%.
Step 8: Continuous Route Optimization
Feed performance analytics back into your routing engine. Automatically demote or disable failing bridge paths, adjust gas buffer calculations, and continuously tune route scoring formulas.
Key Takeaways
Evaluating bridging aggregator performance requires a comprehensive analytical strategy. Evaluating cross-chain systems purely on processed volume or advertised speeds obscures the hidden costs, latencies, and failure modes that impact real-world execution.
-
Performance Is Multi-Dimensional: Comprehensive assessment requires balancing cost, speed, success rate, available liquidity, route quality, and quote accuracy.
-
Averages Can Be Misleading: Always monitor median (P50) and tail-end (P95) percentiles to capture the true user experience and detect edge-case delays.
-
Analyze the Complete Cost Pipeline: Calculate total cost to user by including gas fees on both chains, relayer surcharges, DEX conversion fees, and slippage.
-
Combine On-Chain and Off-Chain Data: Pair immutable blockchain logs with backend API quote records to accurately measure quote-to-execution fidelity.
-
Segment Everything: Evaluate performance across specific chain pairs, token types, transfer size tiers, and timeframes to prevent skewed conclusions.
-
Turn Analytics into Action: Use performance data directly to refine routing algorithms, update gas buffers, and automatically bypass underperforming bridge infrastructure.
Knowing how to track bridging aggregator performance allows teams to move beyond transaction volume and evaluate the actual quality, reliability, cost and efficiency of cross-chain execution.
Frequently Asked Questions
What is the difference between a cross-chain bridge and a bridging aggregator?
A cross-chain bridge is a single protocol that moves assets between blockchains using one specific mechanism—such as a dedicated liquidity pool, lock-and-mint smart contracts, or an intent-based solver network.
In contrast, a bridging aggregator acts as a search engine and smart router built on top of multiple individual bridges and decentralized exchanges (DEXs). Rather than limiting users to a single bridge path, an aggregator queries multiple protocols simultaneously to find the optimal combination of transaction speed, total user cost, and minimal execution slippage.
How do you calculate the actual transaction success rate of a bridge aggregator?
To accurately calculate the success rate of a bridging aggregator, divide the total number of successfully finalized destination-chain transfers by the total number of initiated transfers on the source chain, then multiply by 100:
When tracking this metric, exclude user-cancelled source wallet prompts, but include all transactions that reverted mid-flight, failed due to relayer timeouts, or required manual claim interventions.
What factors cause high transaction failure rates on cross-chain bridge aggregators?
Cross-chain transaction failures typically stem from four main technical bottlenecks:
-
Relayer Timeouts: Message-passing oracles or relayers falling behind during period of high destination-chain traffic.
-
Slippage Violations: Volatile market movements occurring between the user’s initial signature and smart contract execution on the destination DEX.
-
Gas Estimation Failures: Insufficient gas limits passed to the destination chain contract to complete secondary token swaps.
-
Target Pool Depletion: Rapid changes in destination liquidity where the selected bridge pool runs out of unlocked or native assets to fulfill the order.
How do you measure true cross-chain bridging transaction speed?
True bridging transaction speed—also known as end-to-end latency—is measured from the exact block timestamp of the user’s initial signature on the source chain to the final block timestamp on the destination chain where funds are fully accessible in the receiving wallet.
Because block finality rules vary widely across Layer 1s, Layer 2s, and non-EVM chains, speed should always be evaluated using median latency (P50) and 95th percentile latency (P95) rather than simple averages, which mask long tail-end delays.
Why is quote-to-execution accuracy critical for evaluating bridge aggregator efficiency?
Quote-to-execution accuracy measures how closely an aggregator’s initial pre-transaction estimate matches the actual assets received and fees paid upon completion. High variance indicates that an aggregator’s price feeds, gas estimation models, or latency calculations are out of sync with real-time chain state. Measuring this metric prevents hidden slippage, unexpected gas surcharges, and poor user experience caused by inaccurate initial routing quotes.
What is the ideal slippage tolerance for large cross-chain token transfers?
For high-value or institutional cross-chain transfers, slippage tolerance should typically be set between 0.1% and 0.5%, depending on available route liquidity. Setting slippage tolerance higher than 0.5% exposes transfers to sandwich attacks or poor execution on low-depth AMM pools. Setting it too low (below 0.1%) during volatile conditions increases the probability of transaction reverts, resulting in wasted source-chain gas.